



Monday 30 Mar 2026. Nifty closed at 22,331.40, 15.2% under its close of 26,328.55 on 2 Jan. A strategy run through those weeks has one equity curve, and the curve is one draw from many that the same trades could have made. Put the same trades in a different order, or draw them again with replacement, and the worst fall moves a long way. Monte Carlo and bootstrap are the two ways to replay the dice. This lesson shows what each does, why the order of trades changes the drawdown but not the end value, how many replays are enough, and the loudest limit: a resample can never produce a loss the sample does not hold. The runs are models with made up inputs, and nothing here is a view on where Nifty goes.
3By the end you can
- Say how Monte Carlo on odds differs from a bootstrap of trades.
- Show that trade order changes the drawdown and leaves the end value alone.
- Judge the number of paths and the limits of any resampled worst case.
The idea, plainly
What does Monte Carlo do for a strategy?
A backtest gives one path through history. Monte Carlo makes many paths from a stated recipe and reads the spread. The recipe in the model below is a win rate, a payoff ratio and a share of the account risked on each trade. Every simulated trade wins or loses by a seeded random draw, and the account is multiplied up or down. Run 2,000 paths of 250 trades and read the 5th percentile, the median and the 95th percentile of the account at each point, and the share of paths that touch a loss level. It answers a different question from the backtest: not what happened, but how wide the range of outcomes was for the same odds. The inputs come from strategy metrics and the sizing from position sizing.
What is a bootstrap, and how is it different?
A bootstrap needs no win rate. It takes the list of trades the strategy actually made and draws from it at random, with replacement, to build a new list of the same length. The result of each trade is kept as it was, so odd sizes and fat tails in the sample stay. It then runs the account through the new list and records the drawdown and the end value. Repeating this thousands of times gives a distribution that comes from the strategy's own trades, not from a recipe. A plain bootstrap treats trades as independent. If wins and losses come in streaks, a block bootstrap draws runs of consecutive trades instead of single ones.
Maths: the bootstrap, step by step
1. List the n trade results
2. Draw n of them,
each time with replacement
3. Compound the new list
4. Record drawdown, end value
5. Repeat many times
The percentiles of step 4 over the repeats are the answer. The sample is the whole of what the method knows about the strategy, so a sample of 20 trades has at most 20 distinct results to draw from, and the draws can never contain a result that is not in it.
The term this section turns on: Bootstrap
Why does the order of trades matter?
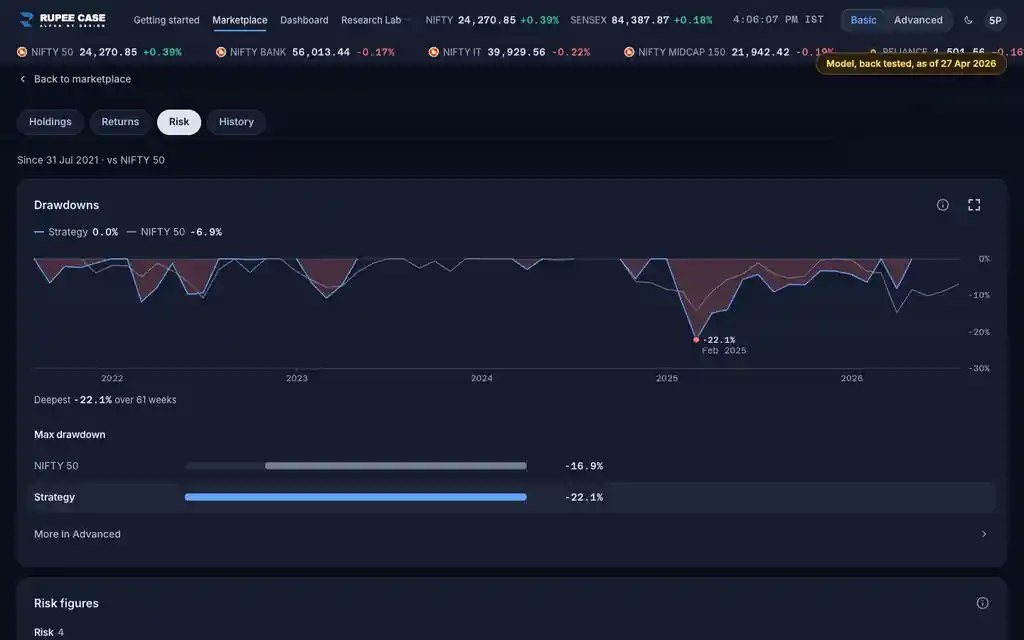
Compounding is multiplication, and multiplication does not care about order. Five wins of three percent and five losses of two percent, in any order, end at 1.05 times the start. What changes is the road. Alternating wins and losses never falls more than 2.0 percent from a peak. Five losses in a row at the start fall 9.6 percent. Losses in a cluster of three and a cluster of two, with a win between, fall 6.9 percent. A real strategy does not choose its order, and a drawdown in a backtest is the one the dates happened to give. Shuffling the order many times shows the range of drawdowns the same trades could have made. It is the cheapest honest check on a backtested drawdown, and its worst shuffles usually fall further than the backtest did.
One set of trades, three orders, three drawdowns
How many paths are enough?
A Monte Carlo answer has its own error. The share of paths that touch a level is an estimate with a standard error that falls with the square root of the number of paths. The table runs the model of the worked example below with five percent of the account risked a trade, at two sizes, and the smaller size with three seeds. A seed fixes the sequence of draws, so the same seed gives the same answer. At 200 paths the answer wobbles by several points between seeds. At 20,000 paths it settles. Quote the paths, the seed and the error with any simulated figure.
| Paths | Seed | Hit the level | Error |
|---|---|---|---|
| 200 | 1 | 46.0% | 3.5% |
| 200 | 2 | 44.0% | 3.5% |
| 200 | 3 | 50.0% | 3.5% |
| 20,000 | 1 | 48.0% | 0.35% |
Maths: the error of a simulated share
SE = square root of
p × (1 − p) ÷ paths
Here p is the share of paths that hit the level. To halve the error, quadruple the paths. At p near one half the error is about one half divided by the square root of the number of paths, so 200 paths give about 3.5% and 20,000 give about 0.35%. The error is only the sampling error of the simulation. It says nothing of whether the inputs are right.
How do I read a simulated range?
Three outputs matter, and they answer different questions. The percentile band says how wide the end values were for the same odds. The share of paths that touch a loss level says how often a given pain arrives on the way. And the distribution of the largest fall says where the backtest's own drawdown sits. If the backtest fell less than almost every simulated path, the history was kind, and the real record should be expected to fall further. If it fell about as far as the middle path, it was ordinary. A backtest drawdown that is better than the simulated median is a caution flag, not a feature. None of this uses the future. It describes how much of a record is the odds and how much is luck.
What can resampling never tell me?
It cannot invent a loss the sample does not hold, and for a seller of far options that is the loss that matters. Take the model of a weekly seller of one far Nifty put, with fair prices. In any week the chance of a loss of more than ten times the premium is 3.4%. In a sample of 20 weeks, the chance that no such week appears is 50 percent. A bootstrap of that sample cannot draw a tail week and will report a tidy distribution. A year of fifty two weeks leaves 17 percent of samples without one, and a hundred weeks 3 percent. The other limits are older. If the trades came from a biased backtest, the resample inherits the bias, and costs, regime changes and dependence between trades are all outside the recipe.
A sample of 20 weeks misses the tail about half the time
Worked example: one edge, many paths
The model has a win rate of 40%, an average win of 1.8 times the average loss and a risk of 3% of the account on each trade. The expectancy is 0.12 R a trade and Kelly is 6.7%. Over 2,000 paths of 250 trades, the median account ends at 1.84 times its start. The weakest twentieth end at 0.68 or less and the strongest at 5.87 or more. A path stops trading when it touches the loss level, which is why the lower line flattens near it. The chance that a path touches a loss of 30% of the account on the way is 24.9%, with a simulation error of 0.97%. Every one of those paths has the same positive edge.
Model, not market data
One edge, a wide band: the weakest twentieth ended at 0.68 times the start
Model, not market data
Same edge, bigger size, a far higher chance of a deep fall
Read one more paragraph, 83 words
Size is the lever. Keep every input and change only the share risked, and the chance of touching that loss changes from 9.9% at two percent a trade to 48.3% at five percent and 78.2% at ten percent. At seven percent a trade, about the Kelly size, it is 64.1%. Kelly and sizing for option strategies takes that up. A strategy is its odds and its size together, and a Monte Carlo that holds only one of them tells half the story.
The common mistake
The belief: I ran ten thousand Monte Carlo paths on my backtest, so I know my worst case.
Ten thousand paths remove sampling noise and add no information. They draw again from the same trades, in a different order, and a sample without a bad week will never produce one. The worst case of a short option strategy sits outside the sample, in a week the data may not hold. Read a Monte Carlo drawdown as a floor on the risk, not a ceiling. Check what the trades came from, whether the backtest was clean, how many trades there are and what the sizing assumes. SEBI allows only registered advisers, research analysts and empanelled algo providers to state past performance, and only as risk and return figures verified by a recognised agency. A simulated range on a screenshot is not that.
Key takeaways
- Monte Carlo shows the spread of paths the same odds could make.
- A bootstrap resamples your own trades and keeps their fat tails.
- Trade order changes the drawdown, not the compounded end value.
- Quote paths, seed and standard error with any simulated figure.
- A resample cannot draw a loss the sample does not hold.
- Read a simulated drawdown as a floor on the risk.
Before you trade. Derivatives trading carries a high risk of loss. SEBI's study "Profitability of Individual Traders in the Equity Derivatives Segment (FY25 to FY26)" (August 2026) found that 87.7% of individual traders in equity F&O made net losses in FY26, with aggregate net losses of Rs 91,685 crore. Read the SEBI study